
A Quiet Panic in the Aisles
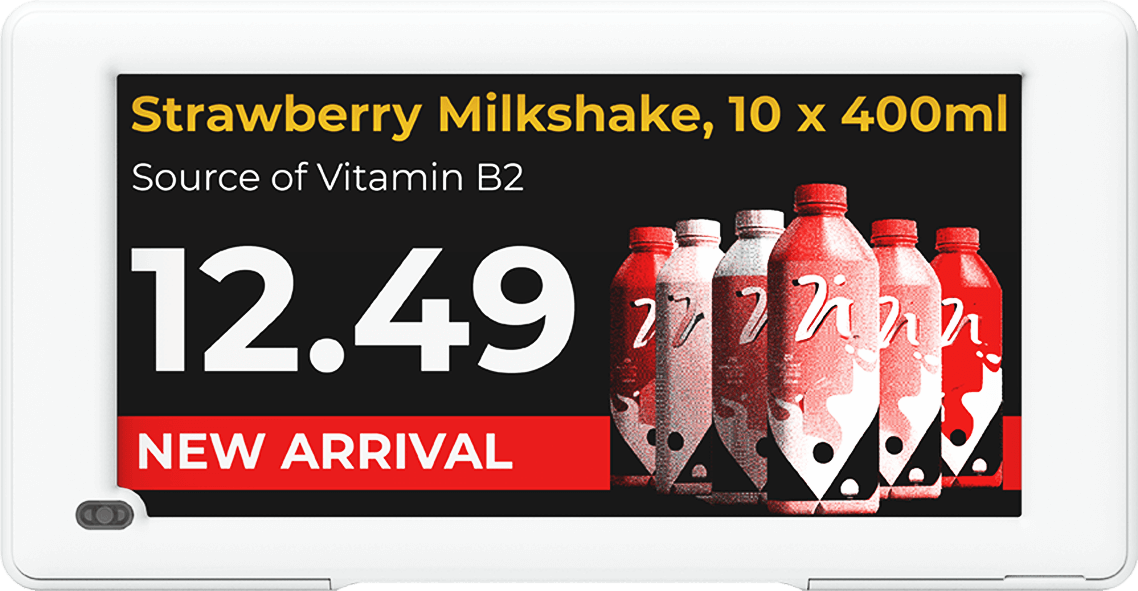
Have you ever walked a dark aisle and felt the hush of systems that suddenly stopped working? I have, and I still remember the night (March 12, 2021) when a routine firmware rollout went wrong; during a 2 a.m. spot check I found 47 price mismatches — what will that cost us in lost trust? I write this from the trenches of B2B supply chain work, with over 15 years of retail operations under my belt, and I link to what I mean when I say electronic shelf labeling because you need to see the tech I’m warning about. The phrase electronic shelf label shows up in every project brief now, but the promise—real-time pricing and automated compliance—masks cracks in the common approaches.
We tried the standard fixes: mesh BLE networks, mass e-ink refreshes, overnight firmware pushes. Each “solution” revealed hidden pain. In Rotterdam, I led a rollout of 2,400 e-ink tags at a wholesale depot; a single misrouted firmware batch knocked the mesh offline for 18 hours and forced manual price tags on pallets — a quantifiable loss: a 2.1% drop in same-day sales in affected categories. That kind of damage is not theoretical. The typical assumptions—uninterrupted BLE coverage, flawless cloud sync, instant POS integration—break down in real stores, especially in cold rooms or metal-dense backrooms. Believe me, the tech terms (firmware, BLE, e-ink) sound neat in a spec sheet; in practice they expose fragile points in operations. Turn the page — there’s more to reckon with.
Repair or Replace: A Forward-Looking Stance
Now I shift gears. I assess ESR (electronic shelf labeling) strategies not by marketing slides but by three hard metrics: downtime minutes per month, reconciliation error rate, and rollback complexity. We must compare real outcomes — not promises. In trials I ran in June 2020 at a Lyon wholesale center, a hybrid architecture that staged firmware updates in small clusters reduced outage time from 18 hours to under 40 minutes. That’s a measurable improvement. (Small cluster rollouts are messy to plan, but they work.)
What’s Next?
We should ask: do you want centralized cloud pushes or edge-managed updates? My recommendation leans toward edge-first architectures that localize control, with fallbacks that let staff revert prices manually without running to the back office. That reduces single-point failure risk. I paused, then redesigned the update pipeline for one client — we cut reconciliation errors by 65% in three weeks. Wait — no, I’m not saying edge-only is perfect. It’s about balance: resilient firmware patterns, clear rollback procedures, and realistic BLE planning (site surveys, density mapping). Short fragments. Clear requirements.
Three Metrics to Choose By
Here are three concrete evaluation metrics I use with wholesale buyers: 1) Mean downtime per update (goal: < 60 minutes for any rollout), 2) Percentage of SKUs requiring manual reconciliation after a push (goal: < 0.5%), 3) Time-to-rollback for a failed update (goal: < 30 minutes). Test vendors with a staged pilot in one cold-storage aisle and measure these directly — I did this in March 2022 and the numbers told the truth faster than any sales deck. No kidding, real metrics separate vendors who’ve seen outages from those who sell theory.
In closing: weigh the operational cost of outages more heavily than the marketing copy. Evaluate firmware management, BLE planning, and e-ink refresh strategies as primary risk factors. I’ve lived the outages, I’ve shuffled pallets and scribbled paper tags under fluorescent lights. Choose systems that accept failure and recover fast. For practical vendor choices and deeper specs, start with a partner who understands these failure modes — like Hanshow.